
 View on Asset Store (opens in new tab)
Package details
- Latest version
- 0.3.0
- Last updated
- First released
- Unity version
- 6000.3.10 or later
- Package size
- 307.1 MB
- Files
- 73
- Favorites
- 14
- Views in the past week
- 50
Price tracking
- Last checked
- Tracked since
- Lowest recorded
- Free on
Keywords
Local Voice LLM
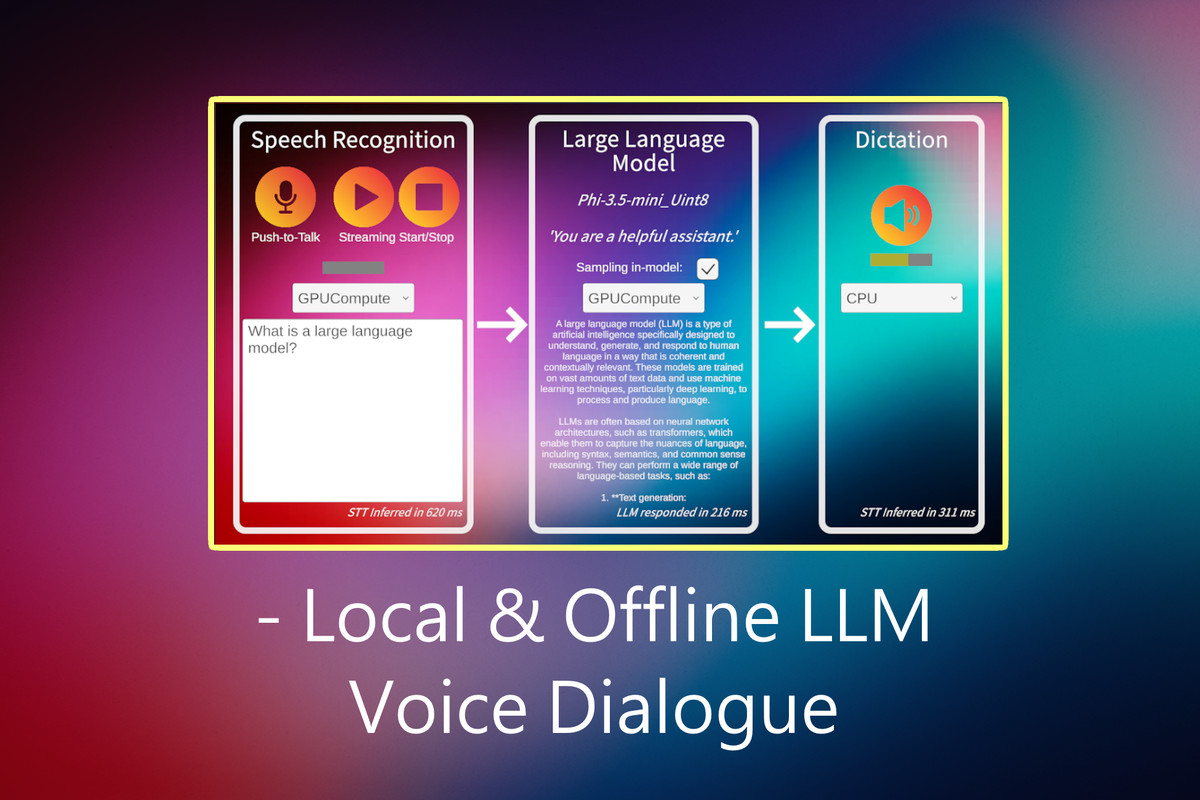
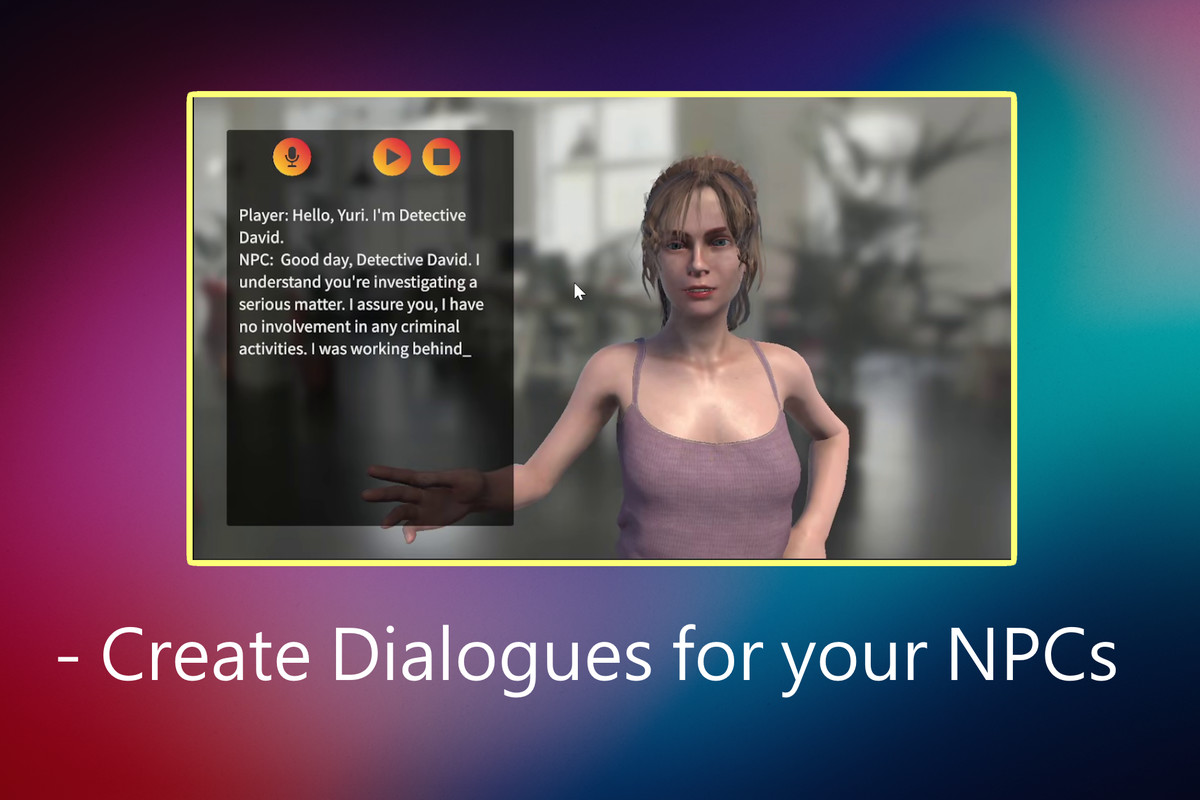
Local, offline, cross-platform voice dialogue with an AI agent using Unity Inference, a Large Language Model (LLM), Speech Recognition (STT) and Text-to-Speech (TTS).
Affiliate link · Purchases support this site
Price history
Last 6 months
USDAsset preview
1 / 4
Local Voice LLM screenshot 1
About this asset
Please check out the WebGPU demo. Inference is done locally - without any network communcation or special libraries required.
LocalVoiceLLM brings together several of my other assets: SimpleOfflineSTT (Speech Recognition), SimpleOfflineLLM (AI agent) and SimpleOfflineTTS (Text-to-Speech) to create a completely local, offline, clean interface for creating a dialogue with a Large Language Model. It's completely offline without any networking or services required.
It does not have any platform-specific code or libraries, so can in theory be used on any platform supported by the Inference package - although memory requirements for running so much through Unity Inference can get high, and desktop and high-end mobile platforms are recommended. Tested on Windows, Android, MacOS and Web using WebGPU.
Please be aware that separate purchases are required for full functionality. You will need at least SimpleOfflineLLM to get Large Language Model support, and either SimpleOfflineSTT (speech recognition) and/or SimpleOfflineTTS (text-to-speech) for the voice interface.
The deployment sizes for several full-precision models can become large, so it's recommended to use uint8 quantized versions to decrease the model sizes to approximately one quarter. With a small (SmolLM2) LLM model, and quantized ONNXs, you can deploy the full system in approximately 350MB.
From the publisher's Asset Store listing.
Technical details
- Requires separate installs for individual functionality of STT, LLM and TTS
- High-quality and local Unity Inference interface - no Python/Libs/Networking
- Cross-platform
- Offline; no networking required
- CPU or GPU-accelerated
- Will run on the Web using WebGPU backend
Compatibility
| Unity version | Built-in | URP | HDRP | Custom |
|---|---|---|---|---|
| 6000.3.10f1 | Compatible | Compatible | Compatible | Compatible |
As listed on the Asset Store.